
Forced Ranking Doesn’t Measure Performance
Forced Ranking Doesn’t Measure Performance. It Manufactures the Behaviour That Destroys It.
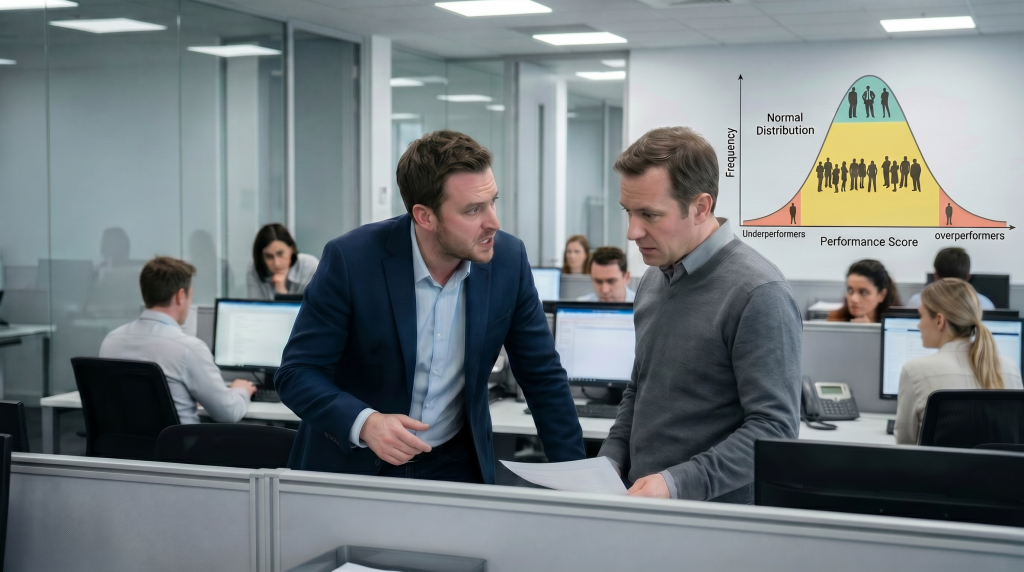
Plenty of organisations still reach for employee ranking in the name of performance. Dressed up as stack ranking, the vitality curve or top-grading, the premise is identical: sort people into a forced distribution, usually with quotas: a fixed top tier, a fat middle, and a bottom tier marked for exit.
The standard critique is that ranking measures badly. That it is too crude to capture complex, collaborative human performance.
That is true, and it lets ranking off too lightly. It treats the practice as a flawed attempt at measurement, when the real damage is something else entirely.
Ranking is an architecture. And it manufactures the exact behaviour that destroys the performance it claims to assess.
The behaviours aren’t side effects
Every well-known pathology of ranking – knowledge hoarding, risk aversion, internal politics, the collapse of collaboration – gets described as an unfortunate consequence. A mood it induces in anxious employees.
That framing misses the mechanism. These behaviours are not a psychological reaction. They are the rational response to what the structure pays off.
When reward is tied to your position relative to your colleagues, helping a colleague stops being a neutral or generous act and becomes a direct cost, because raising their standing lowers yours. So knowledge gets guarded: not because people became selfish, but because the architecture made sharing expensive.
Stretch assignments get avoided, because a visible failure drops you in a distribution where someone has to occupy the bottom. The rational move is the safe task.
Politics intensifies, because where standing is relative and partly subjective, managing your manager’s perception is a higher-return activity than excellent work nobody is positioned to see.
None of this is a culture problem that ranking accidentally creates. It is the behaviour ranking rewards, working exactly as the structure dictates.
A second problem, which would matter even if the behaviour were fine
The measurement ranking claims to provide doesn’t exist.
A forced distribution assumes performance is a stable individual trait that can be sorted onto a curve. But performance is overwhelmingly produced by the architecture a person works inside, not carried around as a fixed property.
Move a bottom-tier performer into a role with clear expectations, adequate support and a structure that fits, and the ranking inverts. The curve measured the fit between person and position far more than it measured the person — then attributed the whole result to the individual, and in many systems dismissed them for it.
And the inputs were subjective to begin with: manager judgement, inconsistent standards, the residue of last quarter’s politics, forced into the false precision of a distribution.
The curve doesn’t reveal a truth about performance. It imposes a shape on it and then treats the shape as a finding.
Why it costs you your best people
The intended logic is that culling the bottom raises the average. The actual effect is usually the reverse.
Routinely removing low performers strips out institutional knowledge, along with the person who would have become excellent if the system had given coaching it never had reason to provide.
But the deeper cost lands at the top. Your strongest people are the ones most able to leave, and many go not because they ranked low, but because they are tired of working inside a zero-sum structure that pits them against colleagues they would rather collaborate with.
The architecture built to identify and keep top performers reliably exhausts and exports them.
Why it survives the evidence
All of which raises an obvious question. Microsoft abandoned stack ranking in 2013. GE eventually walked away from the curve Jack Welch had built his reputation on. The case against ranking is not new, and it is not contested by anyone who has looked at it.
So why does it persist?
Not because the evidence hasn’t reached anyone. Because of what the alternative costs the person who has to use it.
This person was in the bottom tier is a decision with a system behind it. The distribution produced it, the process was followed, and the manager was administering an outcome rather than reaching one.
I don’t think this person is working out is a judgement. The manager owns it personally. It invites a grievance, requires a conversation they would rather avoid, and if it goes wrong, there is nothing to point to except their own assessment.
Ranking is therefore more than pure measurement. It converts a judgement into an administrative result, and transfers the exposure from the person deciding to the instrument they decided by.
This also explains what happens when organisations drop it. The usual replacement is calibration – managers meeting to align their ratings, which in practice means comparing people against each other with a softer vocabulary.
Calibration persists because the relativity was never the point. The protection was. Remove the curve and leave the need for a defensible answer in place, and something curve-shaped grows back within two cycles.
The fix isn’t a kinder ranking
The structural fix is specific: sever the link between an individual’s reward and their position relative to colleagues.
That single change dissolves the pathology, because the pathology was never in the people. It was in the relativity.
When reward depends on the quality of your own work and its contribution to a shared outcome, rather than on out-positioning the person next to you, helping a colleague stops being a cost and becomes part of the job. The safe-task incentive disappears, because failure becomes information rather than a demotion in a forced queue. Politics loses its return, because there is no relative standing to manage.
You don’t have to exhort people to collaborate and take honest risks. You stop paying them to do the opposite, and the behaviour changes on its own.
Concretely, that means three things.
Assess people against the actual requirements of their work and their growth in it, rather than against each other.
Tie individual reward to genuine contribution and to collective outcomes, so that cooperation pays rather than costs.
And treat a struggling performer as a question about fit and architecture: is this the right role, the right support, the right structure, before treating them as a sortable defect.
That last one is the expensive one, and it is where the defensibility problem returns. A manager who investigates fit is doing something harder and less protected than a manager who applies a distribution. If nothing in the structure supports them, they will reach for the curve again, whatever the policy says.
The point
Forced ranking isn’t rigorous, and dropping it isn’t a softening of standards. It is the opposite.
Ranking is the lazy option. It outsources the hard work of building an architecture that produces performance to a distribution that merely sorts people, while manufacturing the behaviour that erodes the thing it claims to measure.
Real rigour is structural. It is building a system in which doing excellent work and helping the people around you do the same is the rational thing to do, and then not needing a curve at all, because the architecture is producing the performance rather than ranking it.